Semantic Caching for LLM Apps: Dual-Layer Architecture Cuts Bills 73%
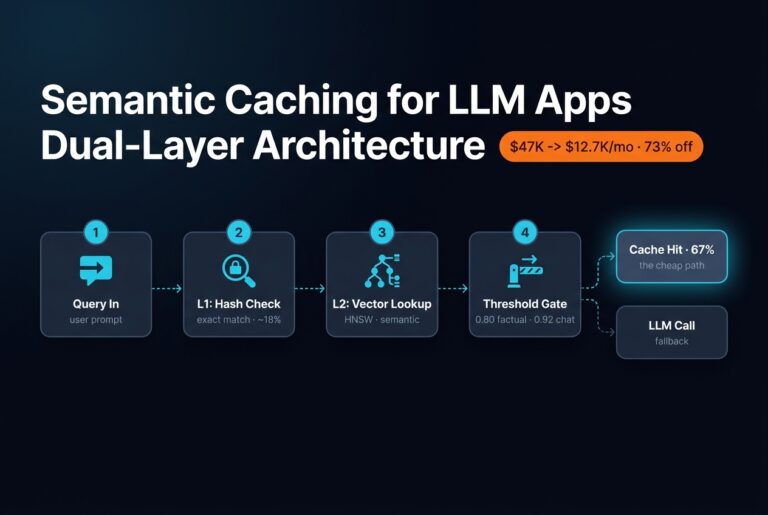
Semantic caching can cut LLM API bills 73%. The dual-layer design: exact hash check, HNSW vector...
Semantic caching can cut LLM API bills 73%. The dual-layer design: exact hash check, HNSW vector...
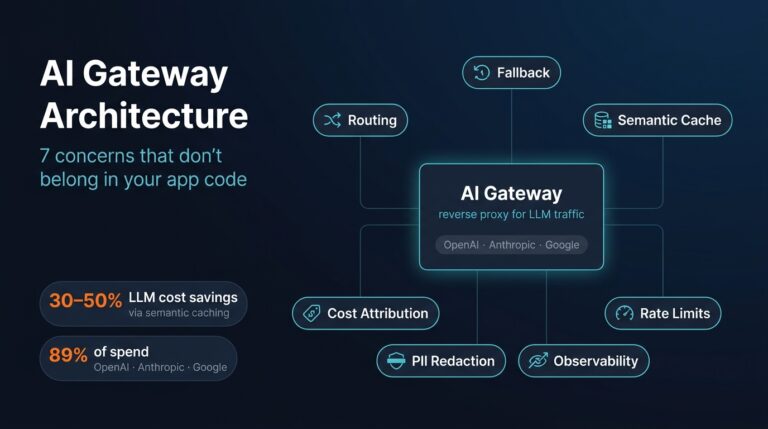
An AI gateway is a reverse proxy built for LLM traffic. Here are the 7 concerns...